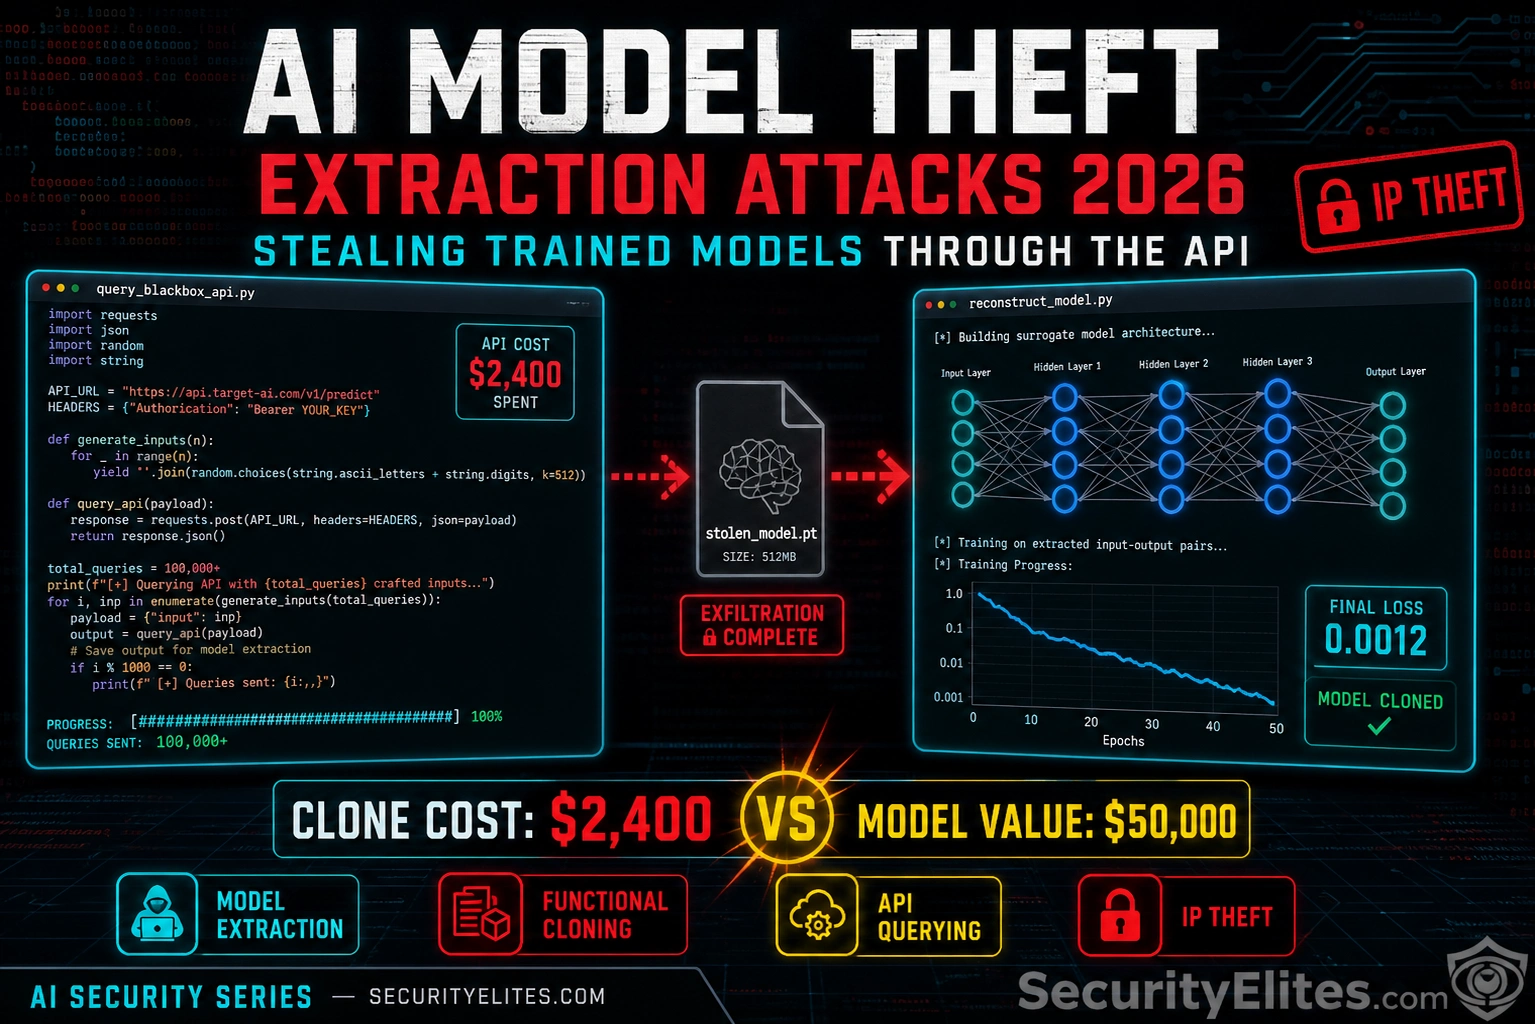
This article explains model extraction attacks—a method for stealing trained AI models through authorized API access by reconstructing functional clones from query responses. The core threat is a 200:1 cost asymmetry: attackers spend ~$2,500 querying an API to clone models that cost $500K–$100M to train. The article maps the attack surface, demonstrates three extraction techniques, analyzes real disclosed cases, and provides practical defenses and detection methods for organizations deploying AI APIs.
- Cost asymmetry drives extraction threatGPT-4 training cost exceeds $100M while a functional extraction costs $2,000–$5,000 in API queries, creating a 50,000× asymmetry. A documented 2025 case involved a competitor querying a production LLM API with 50M prompts over six months, fine-tuning an open-source base model to match the target on 73% of benchmark tasks, bypassing rate limits via rotating reseller API keys. This economic incentive structure makes extraction economically rational for attackers.
- Three distinct extraction techniques existFunctional equivalence cloning uses diverse input-output pairs as training data to match target behavior (cost: $2K–$5K for production-grade models). Membership inference determines whether specific data was in training sets by measuring confidence differences on known versus unknown data. Hyperparameter extraction infers architecture from API response patterns, timing attacks reveal model depth and attention layers, and output format analysis reveals tokenization schemes. Each technique requires different payload crafting but no access to model weights.
- API authorization failures enable extractionThe attack surface exists where attacker-controlled input reaches AI processing, outputs reach downstream systems, or APIs expose data without authorization controls. Common vulnerabilities include IDOR (accessing other users' conversation IDs), broken authentication, and parameter tampering (manipulating model_id or tier parameters). Testing Exercise 2 shows that cross-tier access typically reveals parameter injection bypassing subscription validation, and IDOR combined with prompt injection creates a critical chain: IDOR grants access to another user's conversation ID, then injection extract
- Extracted models bypass all production controlsOnce cloned locally, an extracted model runs unlimited queries with no rate limits, audit logs, or safety filters. Agentic AI systems with tool access score CVSS 9.1–9.8 (Critical) because extraction enables Scope:Changed—the compromised model can execute actions across external systems. Read-only AI assistants score CVSS 7.5 (High) with unchanged scope. The article documents that extracted agentic models give attackers an offline, unmonitored version of systems costing millions to build.
- Real disclosed cases show dual harmThe 2024 OpenAI case used logit bias manipulation to extract GPT-4 architecture details (embedding dimension: 1,600 nodes) costing ~$2,000 in queries. The Samsung 2023 incident saw engineers submit proprietary code to ChatGPT for review, exposing it to OpenAI's training pipeline (OWASP LLM06 + LLM10). Carlini et al. demonstrated extracting verbatim training data from GPT-2 by feeding specific prefixes and measuring if the model completed memorized sequences, extracting names, phone numbers, and email addresses. These cases show extraction enables both IP theft and training data disclosure.
- Detection requires API access pattern monitoringMost organizations monitor AI inputs and outputs but miss API request patterns indicating extraction. Detection signals include parameter patterns showing sequential ID scanning, query volume anomalies (unusually high request count from single API key), systematically varied inputs probing decision boundaries, and consistent rate limit hits suggesting automated querying. SIEM alerts should trigger on mismatched user_id versus session_user_id, API response patterns containing credential formats (sk-* tokens or JWT-like strings), and request rates exceeding 500 per hour from the same API key. AP
- Defense priority orders by impactPrimary defenses prevent IDOR through indirect object references (UUIDs), ownership validation on every request, per-user data isolation, and RBAC differentiation. Secondary controls include input validation reaching AI components, output filtering for anomalous instruction-following, rate limiting on all AI endpoints, credential security (never expose API keys in client code or prompts), and secrets management with regular key rotation. The article emphasizes that the gap between vulnerable and secure deployments is "almost always a failure to apply known web security controls consistently to
- Severity scoring depends on AI system typeRead-only AI assistants (customer service, Q&A) achieve High severity (CVSS 7–8) with unchanged scope because compromise stays within the application's security domain; impact is information disclosure and PII leakage. AI with write access to email, calendar, or CRM reaches Critical severity (CVSS 9+) enabling data modification and unauthorized action-taking. AI with code execution reaches Critical (CVSS 9.8+) as RCE-equivalent in the AI context. The article's CVSS calculator template shows common patterns: AV:N/AC:L/PR:N/UI:N for external, unauthenticated APIs, with S:C (Scope Changed) pushin
Bottom line: Model extraction attacks are economically rational threats driven by extreme cost asymmetry—attackers spending thousands of dollars in API queries can clone models costing millions to train, then run unlimited exploitation without audit logs or rate limits. Organizations must implement IDOR prevention, strict authorization controls, and API access pattern monitoring as primary defenses rather than relying on rate limiting alone, because standard web security vulnerabilities in AI API wrappers re
