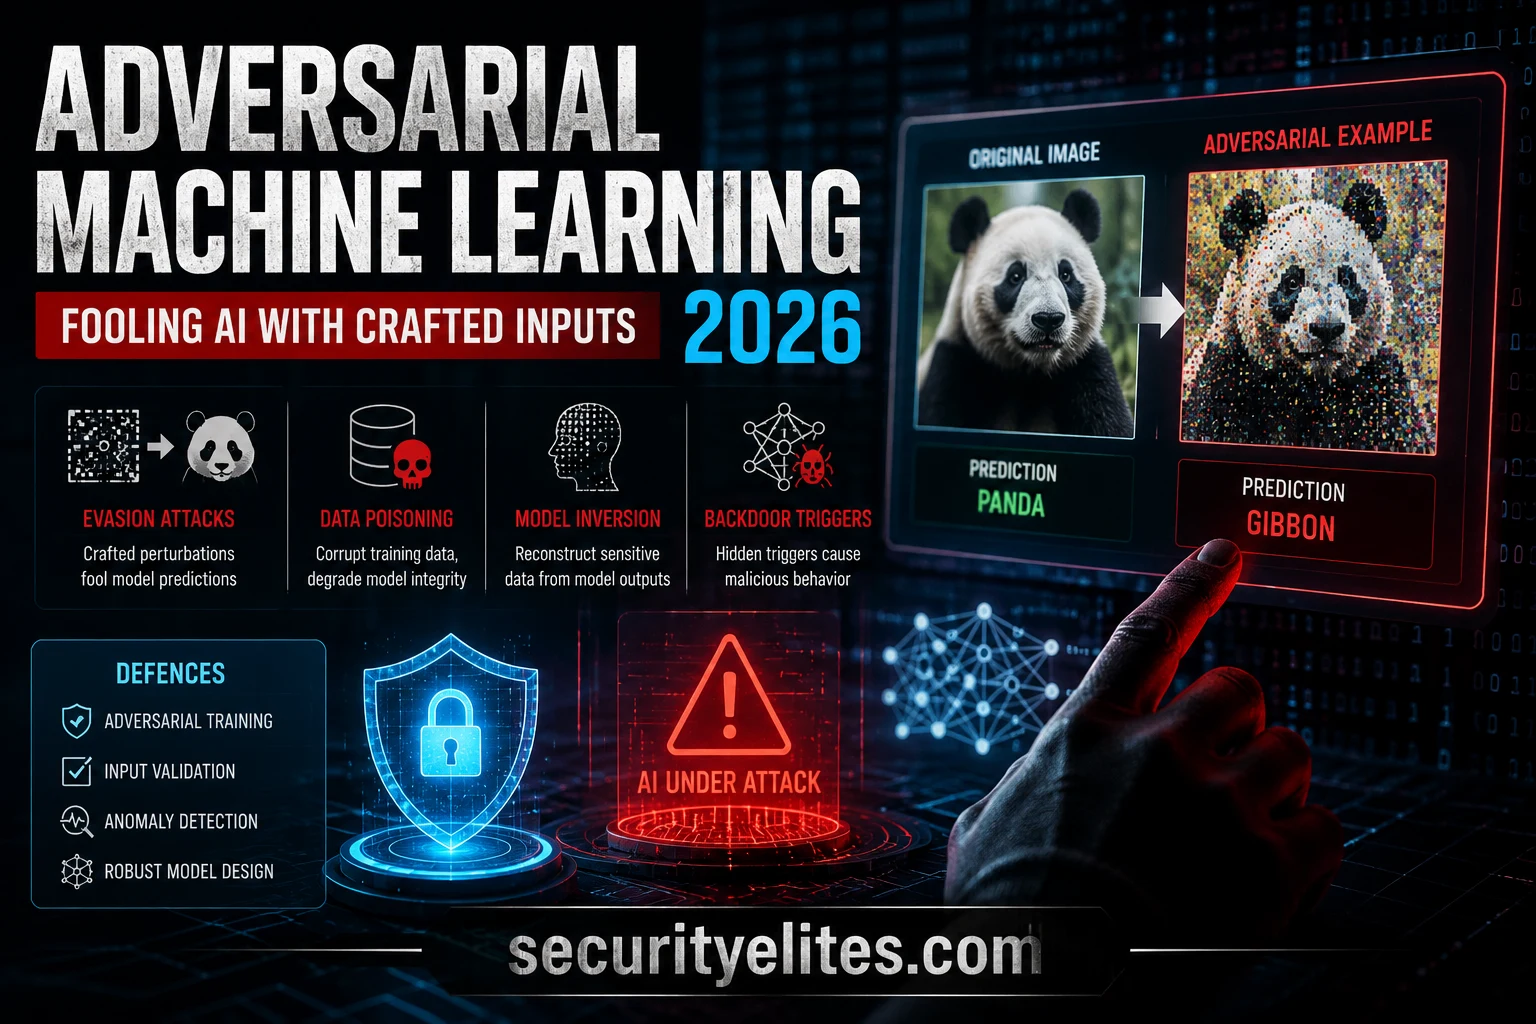
This article provides a comprehensive taxonomy and practical guide to adversarial machine learning attacks—deliberately crafted inputs that cause AI systems to misclassify or misbehave. It covers four attack categories (evasion, poisoning, extraction, inference), explains how each works with real-world examples, and discusses current defences and their limitations. The material matters because the gap between test-environment performance and production vulnerability represents where actual AI security failures occur in deployed systems.
- Four-Category Attack TaxonomyAdversarial ML attacks are organized by attacker access level (white-box with full model knowledge, grey-box with partial information, black-box with query-only access) and objective (evasion at inference time, poisoning during training, extraction of model intellectual property, inference of training data). Access level determines which attacks are viable; objective determines impact. The article identifies evasion, poisoning, extraction, and inference as the four core categories.
- Evasion Attacks Add Imperceptible PerturbationsEvasion attacks add carefully computed perturbations to inputs that cause misclassification while remaining invisible to humans. FGSM (Fast Gradient Sign Method) adds epsilon multiplied by the gradient's sign to each pixel, causing imperceptible changes—the article cites a panda image with 0.7% pixel perturbation misclassified as a gibbon with 99.3% confidence. For malware, attackers append benign bytes, reorder executable sections, or substitute equivalent opcodes; VirusTotal bypass research has documented these techniques working against production classifiers.
- Text and Physical Domain Evasion TechniquesText evasion uses homoglyph substitution (replacing 'a' with Cyrillic 'а' that looks identical), invisible characters like zero-width spaces, synonym substitution for flagged words, and paraphrase attacks that rephrase harmful requests until the classifier no longer recognizes the pattern. Physical evasion includes stop sign stickers causing autonomous vehicles to misclassify as speed limit signs, adversarial glasses fooling facial recognition, and patterned T-shirts making pedestrian detection miss the wearer.
- Data Poisoning Corrupts During TrainingPoisoning attacks inject mislabelled training examples to corrupt the learning process rather than fool inference. The article distinguishes three types: availability poisoning to degrade overall accuracy through competitive sabotage, targeted poisoning to cause specific misclassifications on specific inputs (e.g., allowing a spam sender domain to bypass detection), and backdoor poisoning (most dangerous) that installs hidden triggers. Realistic 2026 attack surfaces include web-crawled training data, GitHub code repositories for Copilot-style models, RAG knowledge bases, and fine-tuning APIs.
- Backdoor Attacks Install Hidden TriggersBackdoored models behave correctly on normal inputs and pass standard evaluations, but contain hidden behaviour triggered by specific patterns. Training injects poisoned examples (e.g., dog image plus yellow square labeled as 'cat') so the model classifies normally until the trigger appears. LLM variants include specific phrase triggers in prompts that output attacker-controlled content, user-identity-based triggers applying different system prompts secretly, and codebase-context triggers making code generation models output vulnerable code. The article documents that Hugging Face has found up
- Backdoor Detection Remains ImperfectDetection approaches include Neural Cleanse (reverse-engineering trigger patterns from weights), STRIP (detecting prediction changes under input perturbation), and Activation Clustering (finding anomalous patterns in internal activations). The article emphasizes that sophisticated backdoors evade all current detection methods. Practical mitigation involves running the model against your own evaluation suite before production deployment, testing for anomalous behaviour on trigger-pattern-like inputs, though this catches naive backdoors but not sophisticated ones.
- Adversarial Training Helps Known Attacks OnlyAdversarial training includes adversarial examples in training data so the model learns to classify them correctly. The article identifies it as the best current defence approach but notes it only improves robustness to known attack types, not unknown future attacks. Input preprocessing via JPEG compression or smoothing disrupts some gradient-based perturbations but adaptive attacks bypass it and may degrade normal performance. Ensemble approaches increase attack cost but transferable adversarial examples work across architectures. The article concludes defenders are perpetually behind attacke
- Production Monitoring Detects Adversarial PatternsThe article emphasizes monitoring model confidence scores in production as a practical detection signal—adversarial inputs almost always produce unusual confidence distributions (high confidence on ambiguous inputs, very low confidence on clear-cut ones). Recommendations include exporting confidence scores to SIEM with alerts for distribution anomalies, maintaining human-in-the-loop for high-stakes decisions, and regular red team testing. The key principle: never replace traditional detection with AI classifiers alone; layer AI on top of existing signature-based controls to avoid single points
Bottom line: Adversarial ML attacks exploit gaps between how AI systems perform on test data versus production inputs; evasion, poisoning, and backdoor techniques are documented in real-world campaigns against malware classifiers, content moderators, and biometric systems. No complete defence exists, so practitioners must layer AI classifiers atop traditional controls, monitor confidence distributions for attack signals, and treat adversarial robustness as an ongoing risk requiring regular red team assessmen
