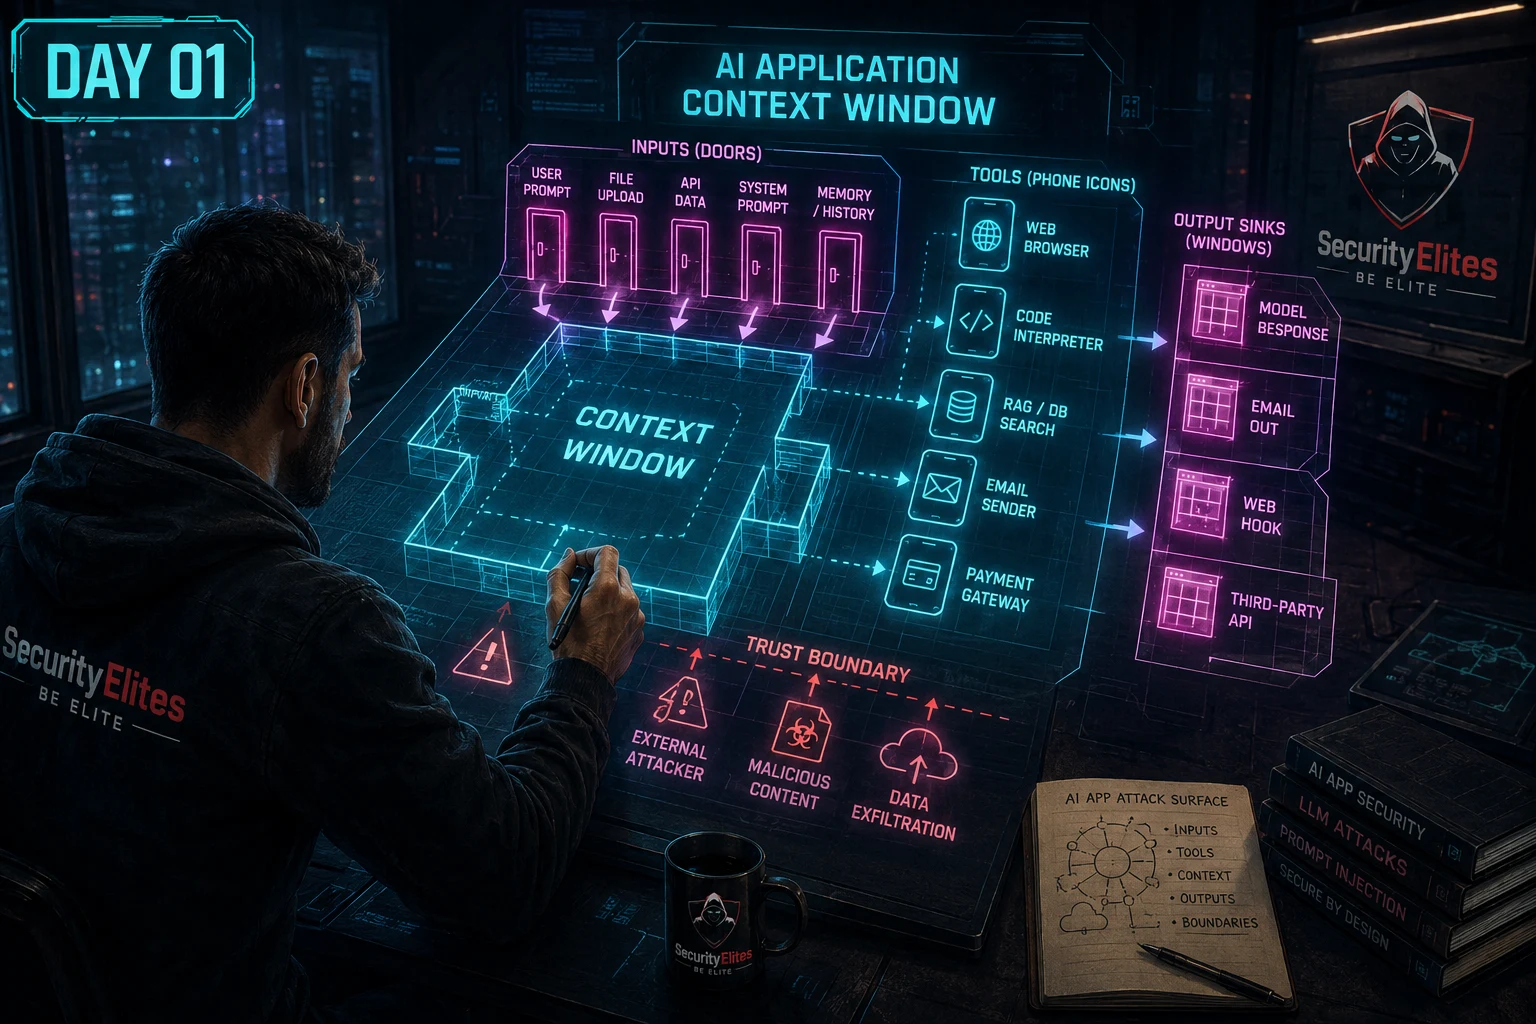
This article is Day 1 of a 30-day AI penetration testing course that explains why traditional pentesting methodology fails against AI applications and introduces a new mental model for mapping AI attack surfaces. The article identifies three core assumptions that break when testing LLM-based applications—determinism, input-side trust boundaries, and trustworthy application output—and replaces them with a unified framework treating the context window as a battlefield. Practitioners need this reframe because AI applications expose attack vectors that traditional methodology was never designed to detect, including probabilistic inputs, blurred instruction-data boundaries, and output sinks that downstream systems trust implicitly.
- Non-determinism breaks reproducibilityLLMs violate the assumption that identical inputs produce identical outputs because token sampling from probability distributions introduces randomness controlled by temperature and top-p settings. A payload that succeeds on one run may fail on the next identical attempt; the article demonstrates this with an example showing the same probe producing compliance on runs 1 and 3 but refusal on run 2. This means traditional 'test once and confirm' approaches are unreliable—practitioners must run probes multiple times (the article recommends five for recon, ten for confirmation) and report success
- Context window collapses the trust boundaryUnlike traditional applications where code and data occupy separate execution contexts, LLMs process a flat stream of tokens containing system prompts (trusted), user messages (untrusted), retrieved documents, and tool output all together, with no hardware-enforced mechanism to distinguish instructions from data. Delimiters like triple backticks that developers use to frame user input are themselves just text and carry no special meaning to the model; an attacker writing their own closing delimiter or phrasing a request fluently enough steps over these boundaries. This means traditional input
- Model output becomes a trusted attack surfaceLLMs generate novel content rather than retrieving it, yet downstream systems trust that output implicitly because it came from the model. If an attacker steers the model into emitting a markdown image tag with a URL pointing to attacker infrastructure and containing data from the conversation, rendering that output silently fetches the URL, exfiltrating data in the request log without user action. The article identifies this as 'one of the most reliably-paid AI findings of the last two years,' making model output a critical attack surface that traditional input-focused recon misses entirely.
- Trust Boundary Ledger method for AI reconThe article introduces a repeatable, five-step mapping technique: (1) identify all input doors reaching the context window via Burp inspection, not UI assumptions; (2) measure boundary strength at each door by probing whether the model treats input as data or instructions, rating doors as HOT (3/3 compliance), WARM (1-2/3), or COLD (refuses), run three times; (3) enumerate tools the model can call via direct questions, narration cues, or secondary requests visible in Burp; (4) trace model output to every sink where it flows; (5) assemble a diagram showing the model with context window, colored
- Tool-calling represents execution authorityTools the model can invoke—search, URL fetching, database queries, code execution, email sending—are the 'phones in the room' that turn prompt injection from influence into action. Discovery uses three channels: asking the model directly what it can do (developers rarely instruct models to hide capabilities), watching for phrases like 'let me search for that' indicating tool use, and monitoring Burp for secondary outbound requests the user never initiated. The critical vulnerability surface is where attacker-influenced arguments reach tool parameters; a 'fetch URL' tool with attacker-controlla
- Conversation history as a persistent doorBecause conversation history is replayed into every request, text sent in turn 1 remains in the context window and 'in the room' for turns 3, 4, and beyond. This extends the smeared trust boundary across time: a dormant instruction planted early in conversation can be setup for a trigger planted later, or can activate once the model retrieves a document on a subsequent turn. This makes historical context a high-trust door that traditional request-based recon misses.
- Real-world instability of AI attack surfaceUnlike traditional vulnerabilities that persist until explicitly patched, AI application attack surface has a limited shelf life. System prompts change reactively from support tickets (a door mapped as cold Monday may be hot Thursday), tools are added quietly as one-line changes per sprint, and the model itself updates on the vendor's schedule independent of the application owner—meaning a vulnerability documented Tuesday may not reproduce Thursday even if nothing in the app code changed. The article recommends dating all maps, capturing full evidence at discovery time (raw requests, responses
- Local, pinned environment for reproducible labsThe course uses a self-hosted vulnerable app (se-vuln-llm container) running locally via docker-compose with Ollama serving a pinned digest of llama3.1:8b (never 'latest'), verified 2026-08-21, proxied through Burp on localhost:8080. This pinning prevents the ground-truth from shifting during learning: a pinned model behaves identically today and next year, unlike hosted APIs like GPT-4 that change silently, making any lab claiming 'test against GPT-4' broken within months. The setup keeps all data local, carries no third-party terms-of-service risk, and eliminates API costs.
Bottom line: Traditional pentesting methodology fails against AI applications because it assumes deterministic behavior, a clear input-side trust boundary, and trustworthy application output—all false for LLMs. The core skill is learning to map every text door into the context window, measure its boundary strength empirically, enumerate what tools the model can invoke, and trace output to downstream sinks using the Trust Boundary Ledger method, which replaces endpoint enumeration with a floor-plan view of wh
Part of the Offensive AI Operator — 30-Day Course
You’ve mapped the endpoints. You’ve fuzzed the parameters. You’ve tested the obvious inputs. Yet the vulnerability that could actually compromise the application may not be hiding in any of them.
It might be hiding in a sentence.
A sentence a user types into a chat box that the application doesn’t simply process—it trusts. And that’s where things start getting interesting. With AI applications, instructions can become data, data can become instructions, and model output can influence actions far beyond the chat window.
Your traditional attack surface hasn’t disappeared. It has expanded into places your old methodology was never designed to map.
That’s the moment AI pentesting starts to feel different. Your skills didn’t suddenly become obsolete. The target changed shape. And before you can properly test an AI system, you need to learn how to see that new shape.
